humanizer
GPT Humanizer
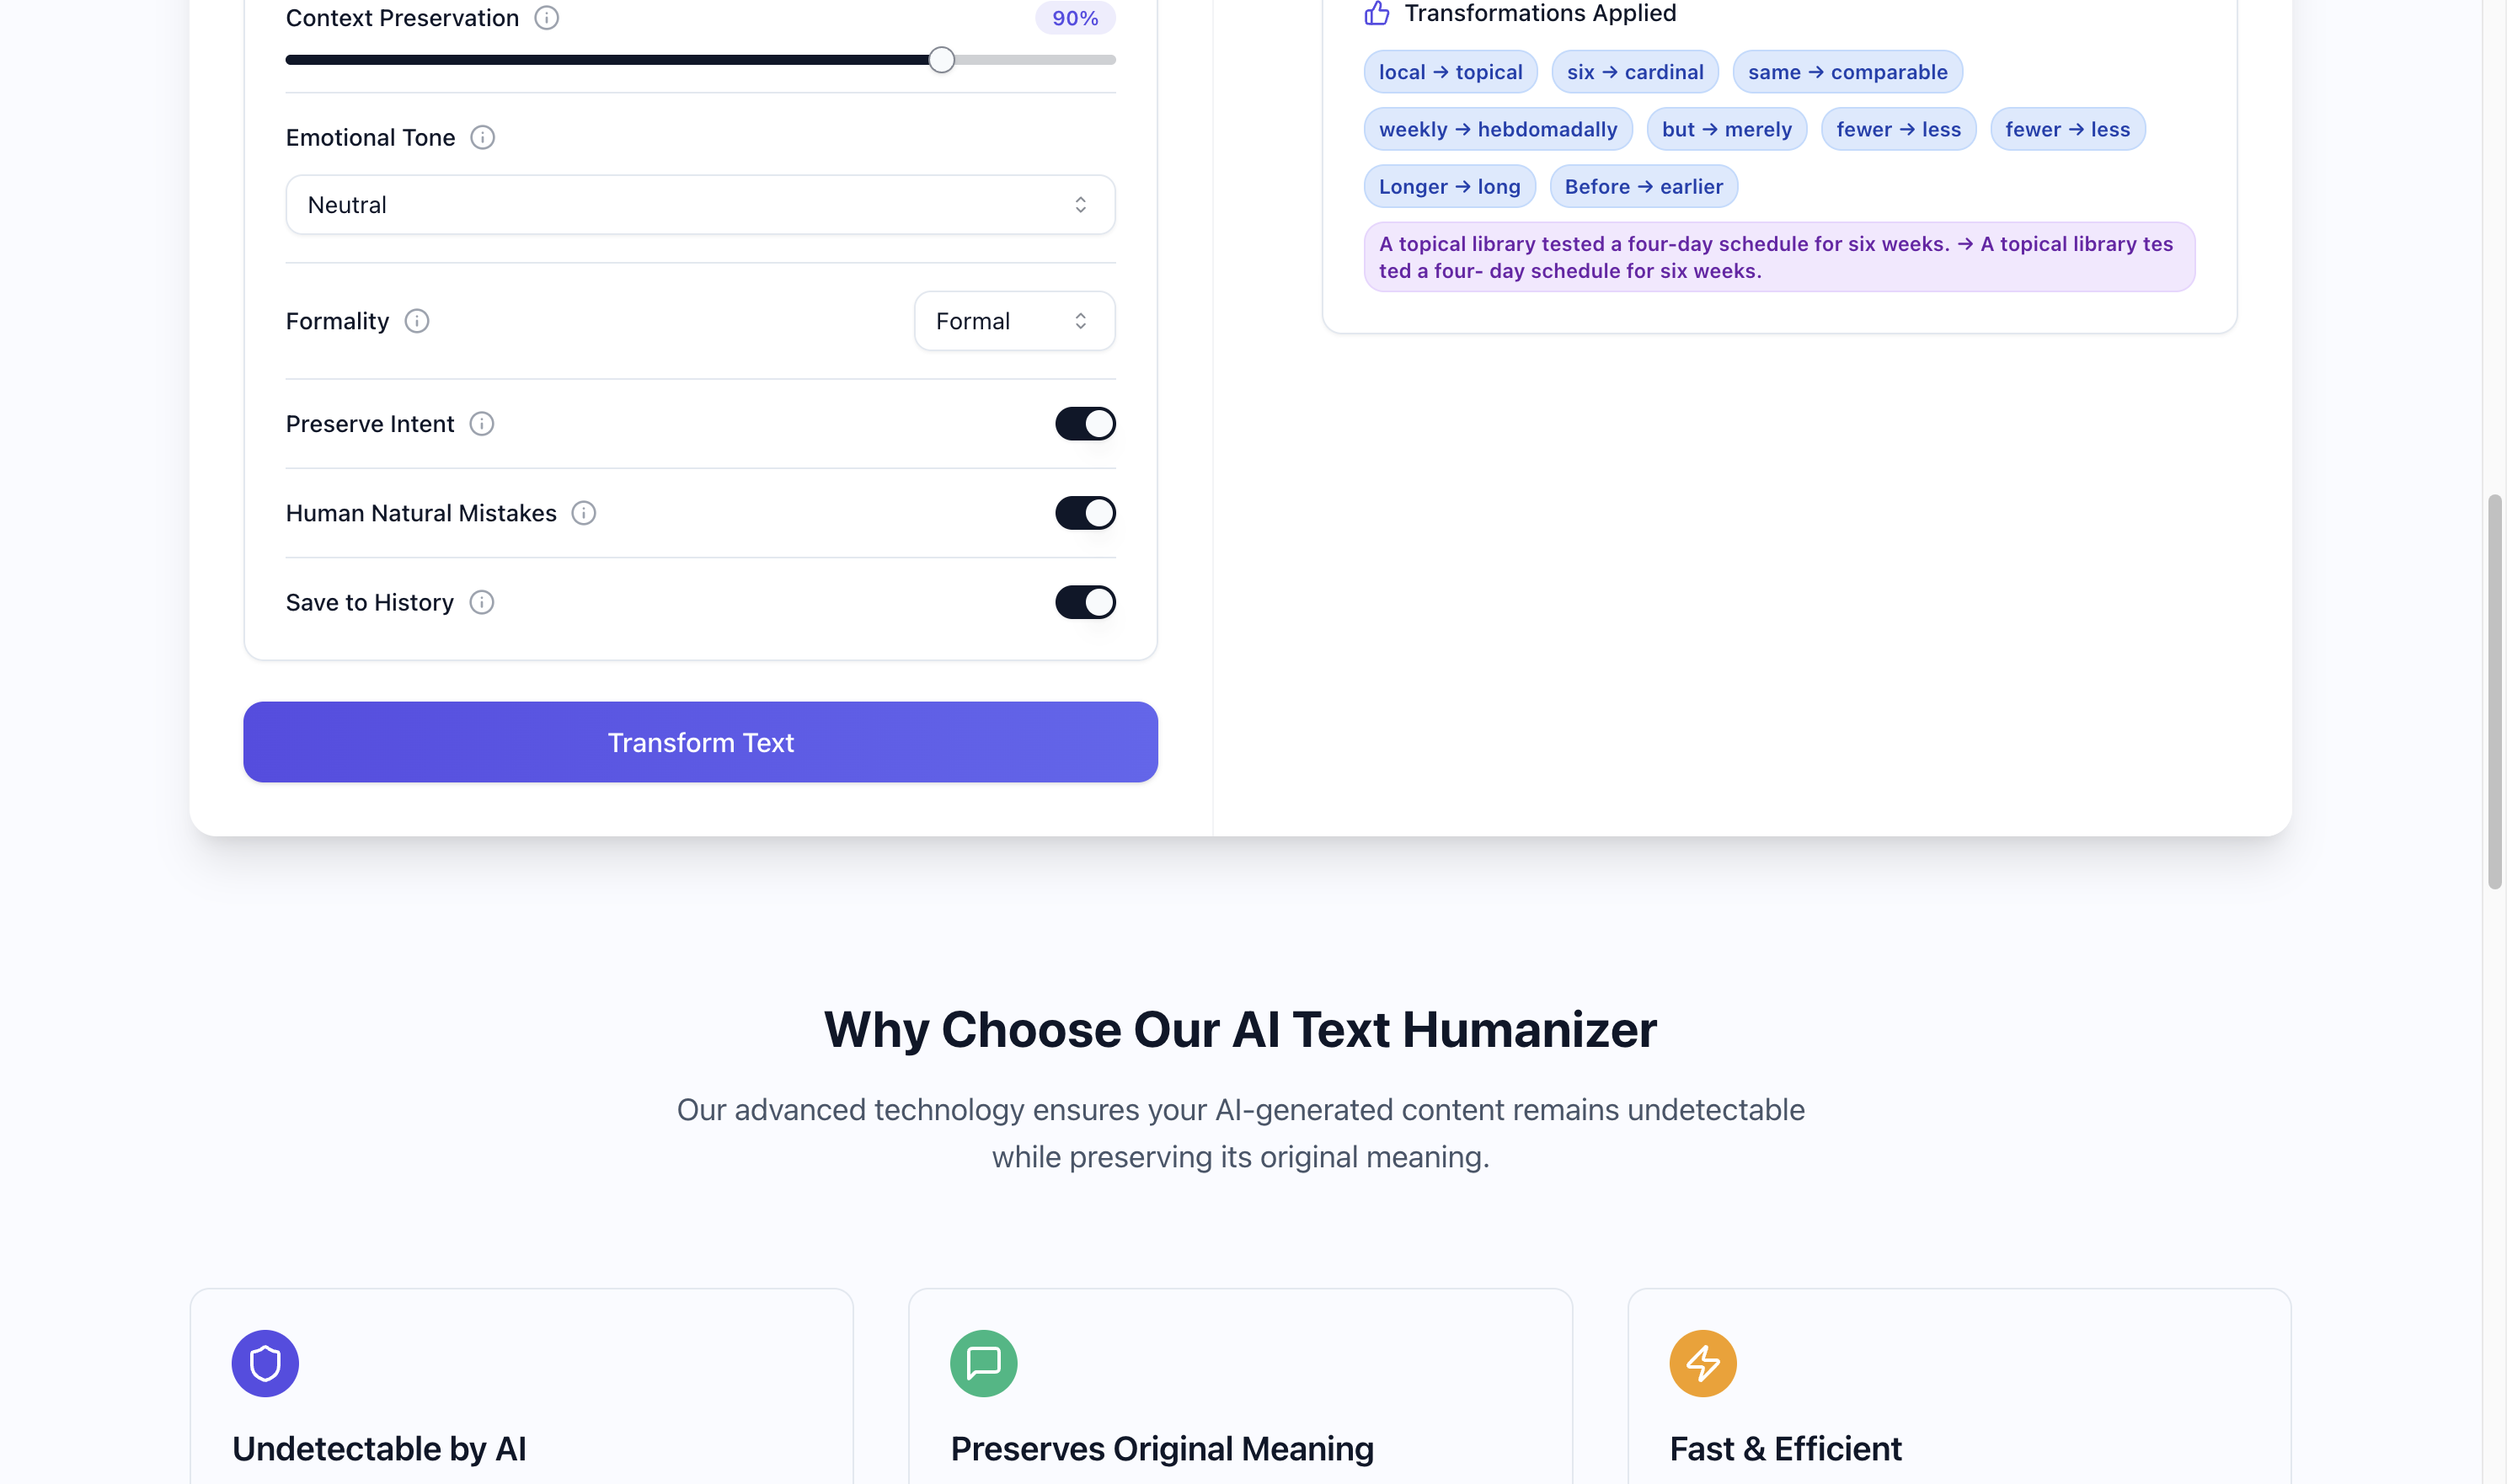
With Human Natural Mistakes enabled by default, the result changed local to topical and added punctuation problems. The transformation log was less reliable than reading the actual output.
Website screenshot
Original and rewritten result
Creativity 60% / Context 90% / Neutral / Formal / default toggles on. Same benchmark; first complete output. Open any screenshot to inspect the original capture.
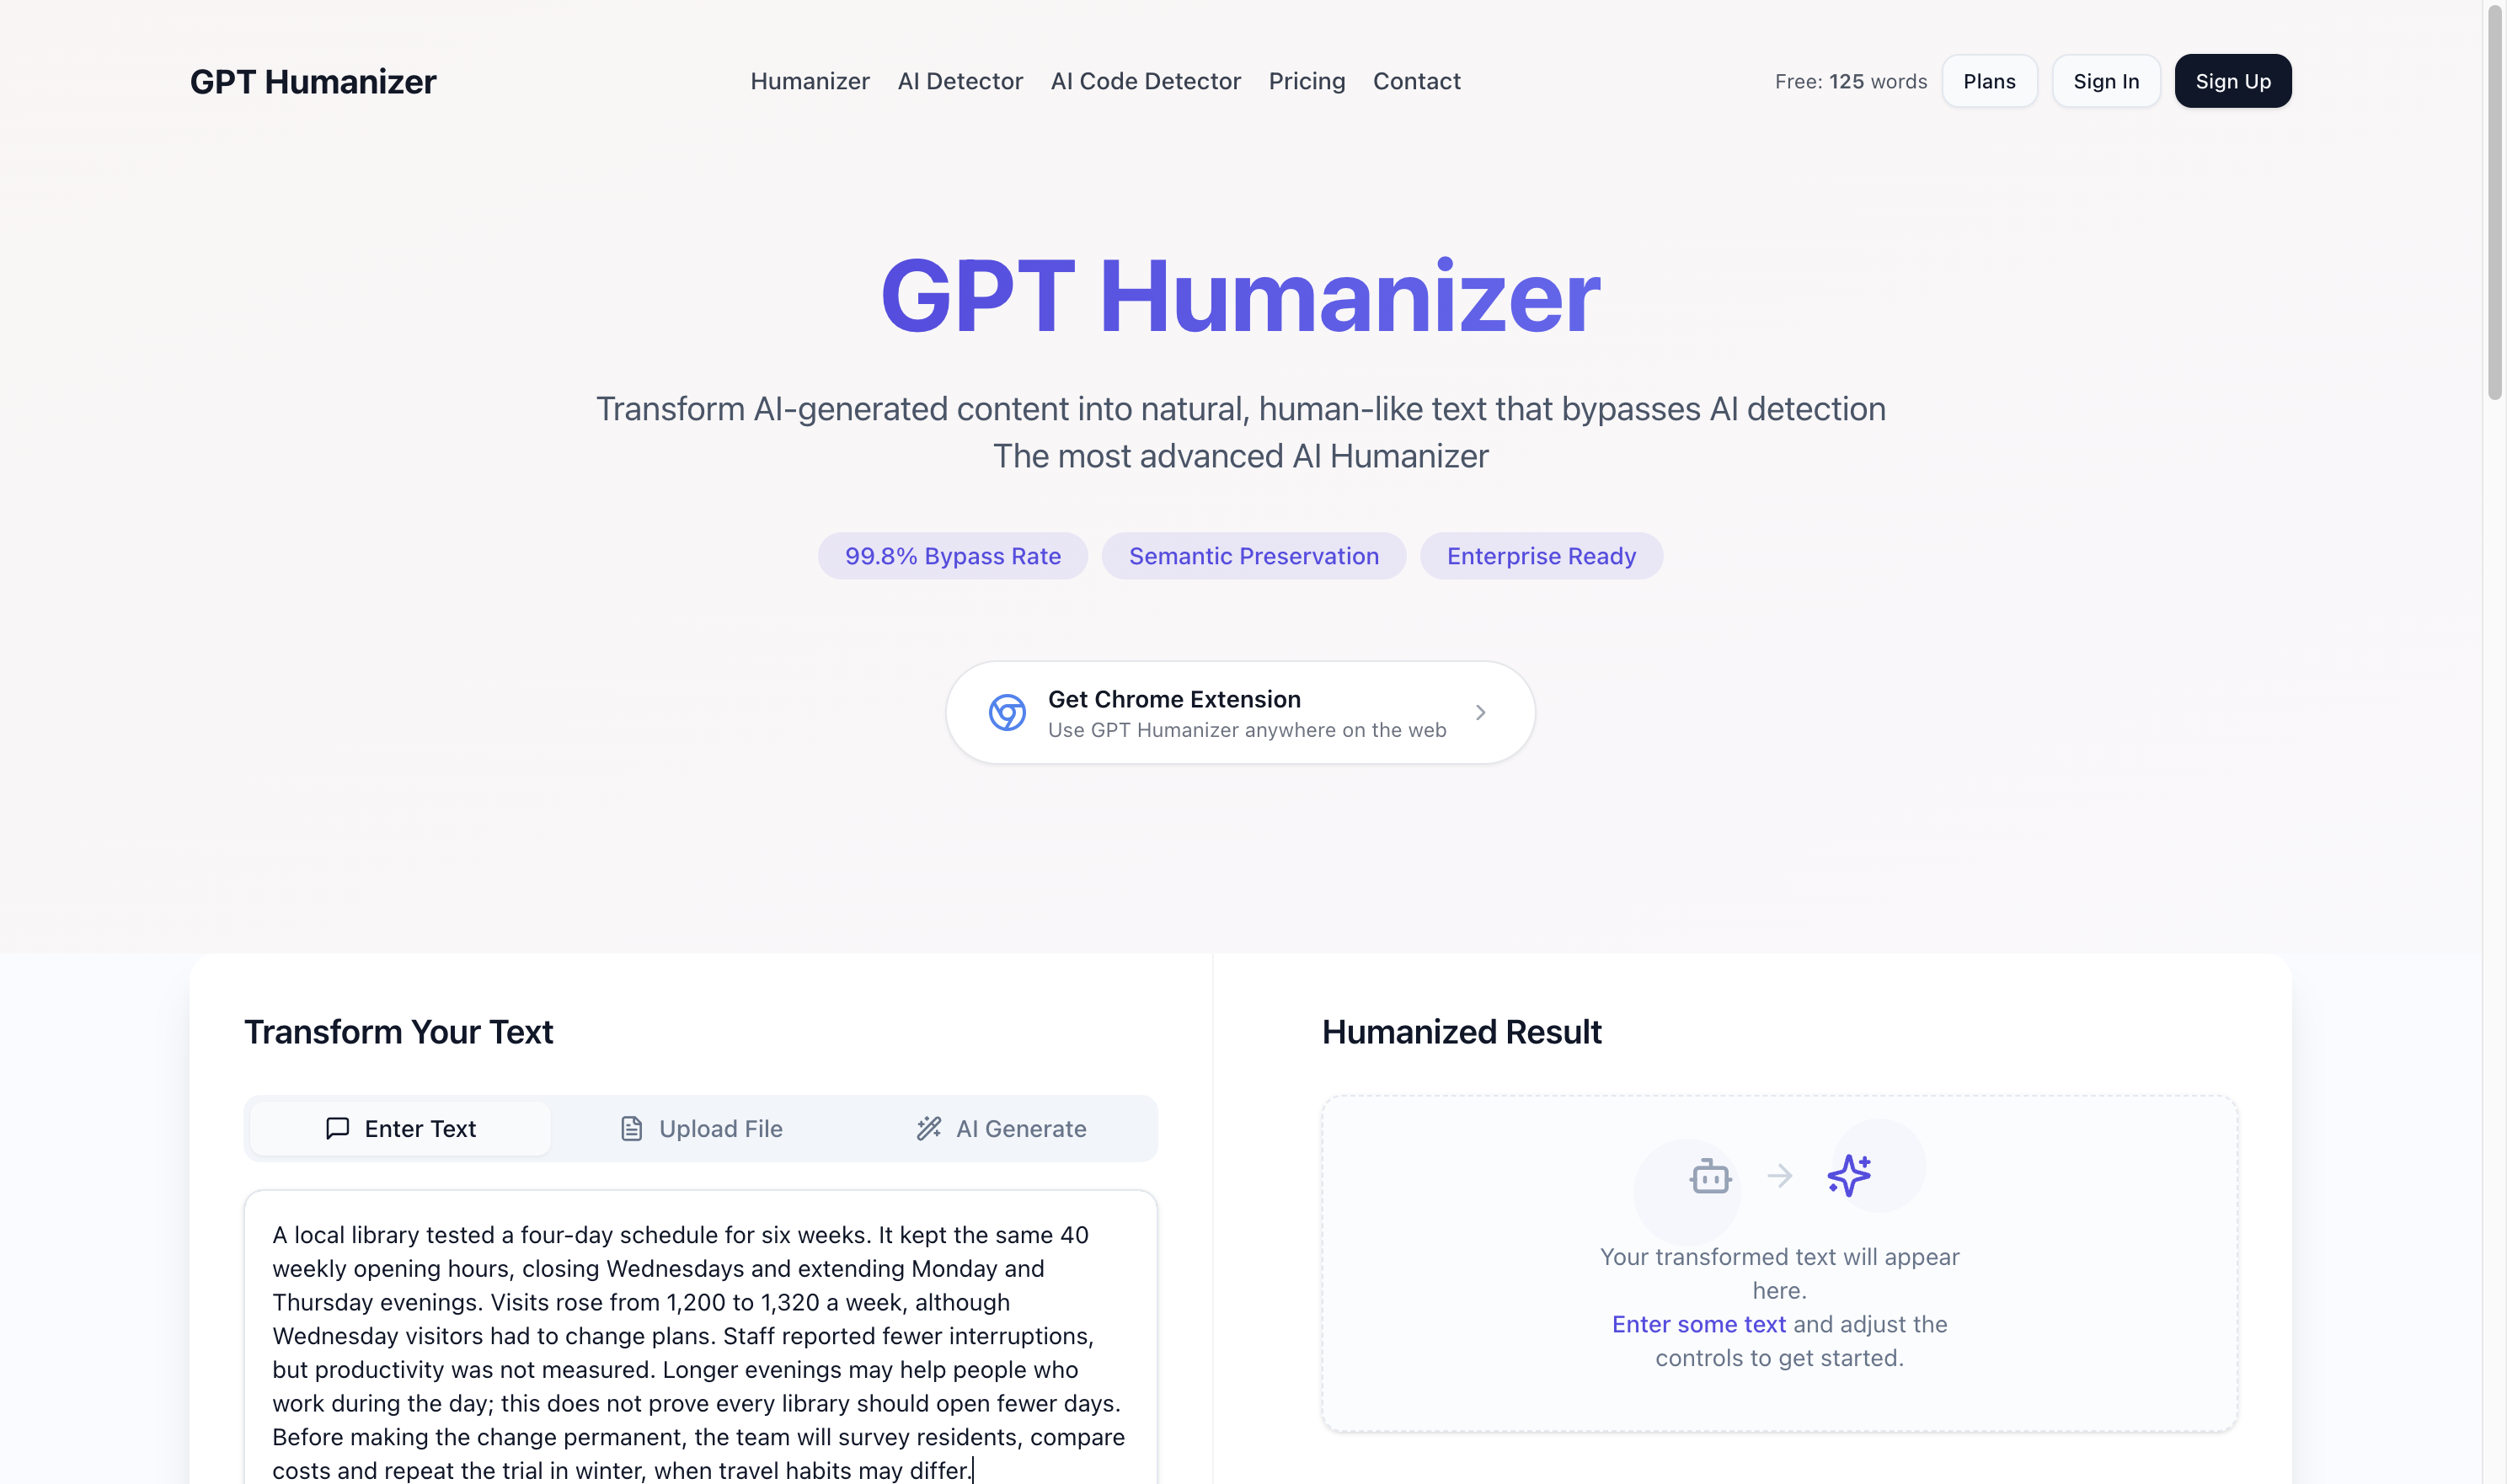
Original · 93 words
A local library tested a four-day schedule for six weeks. It kept the same 40 weekly opening hours, closing Wednesdays and extending Monday and Thursday evenings. Visits rose from 1,200 to 1,320 a week, although Wednesday visitors had to change plans. Staff reported fewer interruptions, but productivity was not measured. Longer evenings may help people who work during the day; this does not prove every library should open fewer days. Before making the change permanent, the team will survey residents, compare costs and repeat the trial in winter, when travel habits may differ.
First rewrite
A topical library tested a four day schedule for six weeks . It kept the comparable 40 weekly opening hours , closing Wednesdays and extending Monday and Thursday evenings . Visits rose from 1,200 to 1,320 a week, although Wednesday visitors had to change plans . Staff reported fewer interruptions, but productivity was not measured. long evenings may help people who work during the day; this does not prove every library should open fewer days . Before making the change permanent, the team will survey residents, compare costs and repeat the trial in winter, when travel habits may differ .
Parameters and feature comparison
Observed features refer to the tested plan. “Not verified” is different from “not supported.”
| Parameter | GPT Humanizer |
|---|---|
| Free access | 125-word free allowance displayed; after this 93-word run the interface showed 32 remaining. |
| Account required | No, for this completed guest run. |
| One-click rewrite | Yes, the complete sample produced a full output. |
| Word highlighting | No word-by-word change display verified in this workflow. |
| Line / sentence highlighting | No separate line or sentence change diff verified. |
| Selective rewriting | Not verified in the tested workflow. |
| API / MCP / Agent Skills | No official humanizer API, MCP or agent skill verified in the reviewed material. |
| Paid plans | Pro $9.99/month lists 30,000 words per transformation. Team $29.99/month lists unlimited transformation words and API access. No paid checkout or API test. |
| Billing unit | Pricing describes words per transformation; the guest interface also shows a remaining balance. Renewal of that balance was not verified. |
Score breakdown
| Dimension | Weight | Score | What we found |
|---|---|---|---|
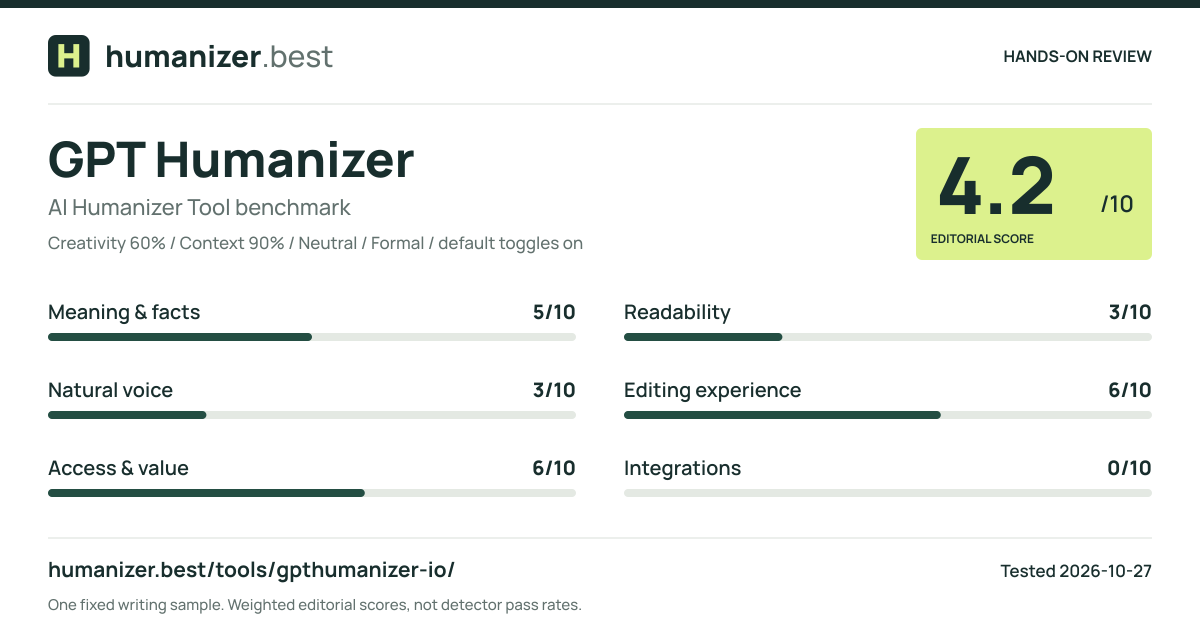
| Meaning & facts | 30% | 5/10 | Changed local to topical and same hours to comparable; other core figures remained. |
| Readability | 25% | 3/10 | Extra spaces before punctuation and lowercase sentence starts require repair. |
| Natural voice | 15% | 3/10 | Artificial mistakes and odd synonyms make the output feel forced. |
| Editing experience | 15% | 6/10 | Complete output and Copy, with a transformation log; the log does not always match the actual final wording. |
| Access & value | 10% | 6/10 | Guest sample worked, but remaining balance and per-transformation pricing language need distinguishing. |
| Integrations | 5% | 0/10 | Team plan advertises API access, but endpoint documentation was not verified. |
Overall 4.2/10 · weighted editorial judgment of the shown workflow. Read the method.
GPT Humanizer review: when natural mistakes create extra editing
With Human Natural Mistakes enabled by default, the result changed local to topical and added punctuation problems. The transformation log was less reliable than reading the actual output.
Read the analysis and recommendationSources and limits
- Official editor, settings and transformation log · checked 2026-10-27
- Official plan comparison · checked 2026-10-27
One short English sample and the first captured output in the stated mode. Paid models, long documents, external detectors and live integrations were not tested. Pricing is a dated snapshot; documentation is not an end-to-end integration test.